

Metabolism is the set of life-sustaining chemical reactions in organisms that allows them to grow, reproduce, maintain their structures, and respond to their environments. To study how these metabolic processes change in different conditions, scientists use genome-scale metabolic models (GEMs). GEMs are like comprehensive blueprints that list all the metabolic genes and the reactions they control in an organism, but they don’t specify conditions like age or disease state.
However, researchers often need to focus on specific conditions, such as cancer or Alzheimer’s disease, to understand how metabolism changes in those scenarios. This is where RNA sequencing (RNA-seq) comes in. RNA-seq helps scientists see which genes are turned on or off in a particular tissue under specific conditions. By combining this information with GEMs, scientists can create tailored metabolic models that reflect the unique metabolic activities of diseases.
Two commonly used algorithms to create these condition-specific models are iMAT (Integrative Metabolic Analysis Tool) and INIT (Integrative Network Inference for Tissues). They use RNA-seq data to make GEMs more relevant to specific diseases. However, how scientists prepare or “normalize” the RNA-seq data can significantly impact the resulting metabolic models. Researchers at the Gebze Technical University aimed to evaluate five different RNA-seq normalization methods: TPM (Transcripts Per Million), FPKM (Fragments Per Kilobase of transcript per Million mapped reads), TMM (Trimmed Mean of M-values), GeTMM (Generalized TMM), and RLE (Relative Log Expression).
Workflow for the study
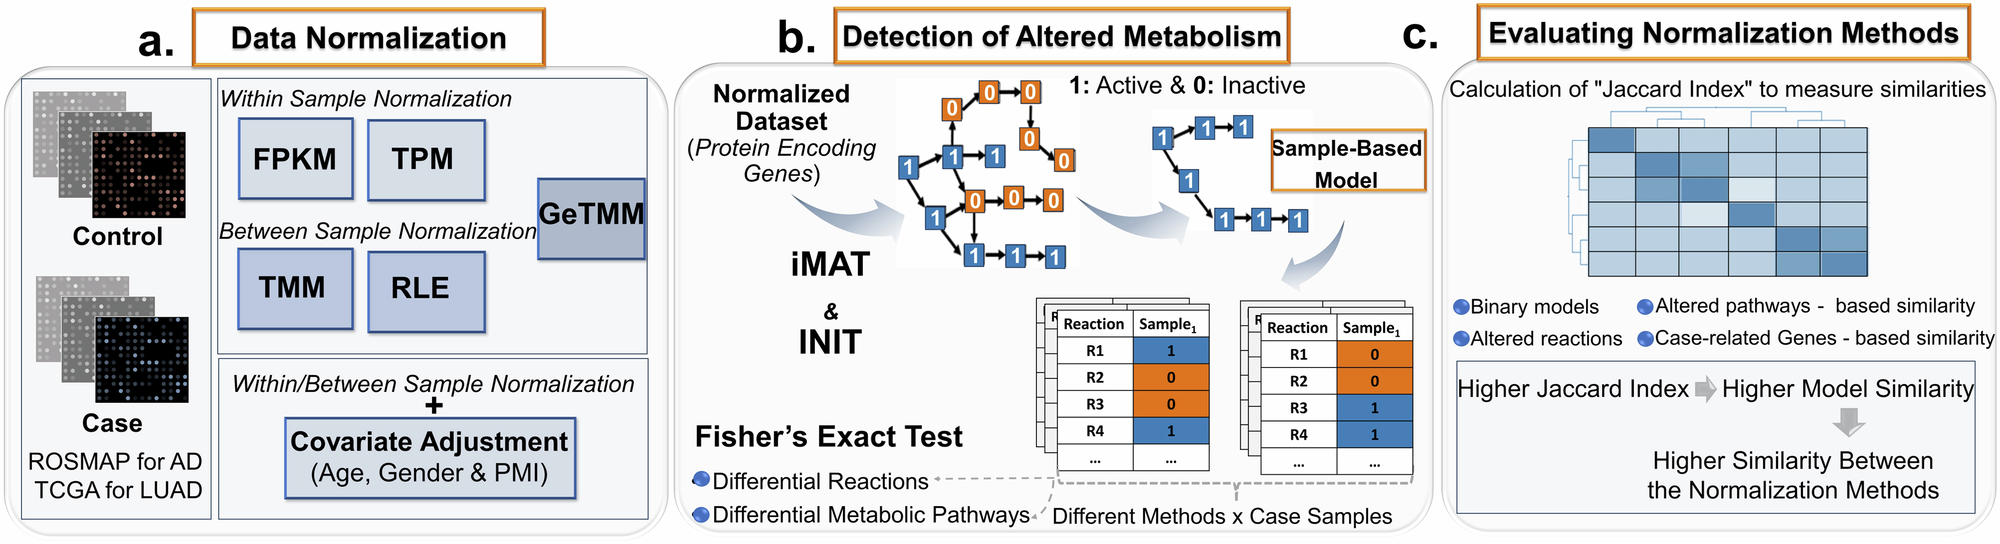
a The researchers used FPKM, TPM, TMM, RLE, and GeTMM methods for the normalization of two datasets: ROSMAP for AD, and TCGA for LUAD. We also used covariate adjustment for both datasets. b iMAT and INIT were used for the integration of transcriptome data into the metabolic model. Generated personalized metabolic models were binarized and Fisher’s exact test was performed to determine significantly affected reactions/pathways. c The similarity of normalization methods was evaluated using the Jaccard similarity index.
To investigate the best method for creating accurate metabolic models, the researchers analyzed RNA-seq data from patients with Alzheimer’s disease and lung adenocarcinoma (a type of lung cancer). They found that normalization methods like RLE, TMM, and GeTMM produced more consistent and reliable models with fewer false predictions compared to methods like TPM and FPKM. In practical terms, this means that the RLE, TMM, and GeTMM methods allowed the scientists to better identify genes associated with these diseases, achieving an accuracy of about 80% for Alzheimer’s disease and 67% for lung adenocarcinoma.
Additionally, when the researchers adjusted the data for factors like age and gender, they noticed that all methods became more accurate. This adjustment is essential because factors such as age and gender can significantly influence gene expression and, consequently, the metabolic processes involved in diseases.
The study concludes that while some normalization methods may miss identifying certain important genes (true positives), they help reduce incorrect predictions (false positives). This research provides valuable insights into how to best utilize RNA-seq data in creating personalized metabolic models for diseases, paving the way for more precise treatments and interventions in the future.
By understanding how different normalization methods affect the creation of GEMs, scientists can make better predictions about disease mechanisms and improve our knowledge of metabolic changes that occur in various health conditions.
Lüleci HB, Uzuner D, Cesur MF, İlgün A, Düz E, Abdik E, Odongo R, Çakır T. (2024) A benchmark of RNA-seq data normalization methods for transcriptome mapping on human genome-scale metabolic networks. NPJ Syst Biol Appl 10(1):124. [article]
Related Posts





Metabolism is the set of life-sustaining chemical reactions in organisms that allows them to grow, reproduce, maintain their structures, and respond to their environments. To study how these metabolic processes change in different conditions, scientists use genome-scale metabolic models (GEMs). GEMs are like comprehensive blueprints that list all the metabolic genes and the reactions they control in an organism, but they don’t specify conditions like age or disease state.
However, researchers often need to focus on specific conditions, such as cancer or Alzheimer’s disease, to understand how metabolism changes in those scenarios. This is where RNA sequencing (RNA-seq) comes in. RNA-seq helps scientists see which genes are turned on or off in a particular tissue under specific conditions. By combining this information with GEMs, scientists can create tailored metabolic models that reflect the unique metabolic activities of diseases.
Two commonly used algorithms to create these condition-specific models are iMAT (Integrative Metabolic Analysis Tool) and INIT (Integrative Network Inference for Tissues). They use RNA-seq data to make GEMs more relevant to specific diseases. However, how scientists prepare or “normalize” the RNA-seq data can significantly impact the resulting metabolic models. Researchers at the Gebze Technical University aimed to evaluate five different RNA-seq normalization methods: TPM (Transcripts Per Million), FPKM (Fragments Per Kilobase of transcript per Million mapped reads), TMM (Trimmed Mean of M-values), GeTMM (Generalized TMM), and RLE (Relative Log Expression).
Workflow for the study
a The researchers used FPKM, TPM, TMM, RLE, and GeTMM methods for the normalization of two datasets: ROSMAP for AD, and TCGA for LUAD. We also used covariate adjustment for both datasets. b iMAT and INIT were used for the integration of transcriptome data into the metabolic model. Generated personalized metabolic models were binarized and Fisher’s exact test was performed to determine significantly affected reactions/pathways. c The similarity of normalization methods was evaluated using the Jaccard similarity index.
To investigate the best method for creating accurate metabolic models, the researchers analyzed RNA-seq data from patients with Alzheimer’s disease and lung adenocarcinoma (a type of lung cancer). They found that normalization methods like RLE, TMM, and GeTMM produced more consistent and reliable models with fewer false predictions compared to methods like TPM and FPKM. In practical terms, this means that the RLE, TMM, and GeTMM methods allowed the scientists to better identify genes associated with these diseases, achieving an accuracy of about 80% for Alzheimer’s disease and 67% for lung adenocarcinoma.
Additionally, when the researchers adjusted the data for factors like age and gender, they noticed that all methods became more accurate. This adjustment is essential because factors such as age and gender can significantly influence gene expression and, consequently, the metabolic processes involved in diseases.
The study concludes that while some normalization methods may miss identifying certain important genes (true positives), they help reduce incorrect predictions (false positives). This research provides valuable insights into how to best utilize RNA-seq data in creating personalized metabolic models for diseases, paving the way for more precise treatments and interventions in the future.
By understanding how different normalization methods affect the creation of GEMs, scientists can make better predictions about disease mechanisms and improve our knowledge of metabolic changes that occur in various health conditions.
Lüleci HB, Uzuner D, Cesur MF, İlgün A, Düz E, Abdik E, Odongo R, Çakır T. (2024) A benchmark of RNA-seq data normalization methods for transcriptome mapping on human genome-scale metabolic networks. NPJ Syst Biol Appl 10(1):124. [article]
Related Posts
Recent Posts
 Benchmarking RNA sequencing for more accurate alternative splicing analysis
 RNA Sequencing identifies new tick-borne virus that causes flu-like illness
 Eclipsebio expands its RNA characterization capabilities with multi-attribute nanopore-based sequencing assay eSTRAND RNA QC™
 Single-cell RNA sequencing links genetic mutations to cell behavior in cancer
 Small RNA sequencing reveals regulatory roles for sdRNAs in acute myeloid leukemia
 Creative Biolabs expands advanced single-cell multi-omics and RNA sequencing solutions to support biomedical discovery
RNA-Seq Products & Services


Stay Connected