

RNA sequencing, or RNA-seq, provides a snapshot of which genes are active in a biological sample at the time it is collected. Record-seq takes a different approach. Instead of measuring RNA directly at one moment, it allows engineered bacteria to create a molecular record of their transcriptional activity over time.
A research team from ETH Zurich, Switzerland, have developed a new computational framework specifically for analyzing Record-seq data.
End-to-end Record-seq analysis framework
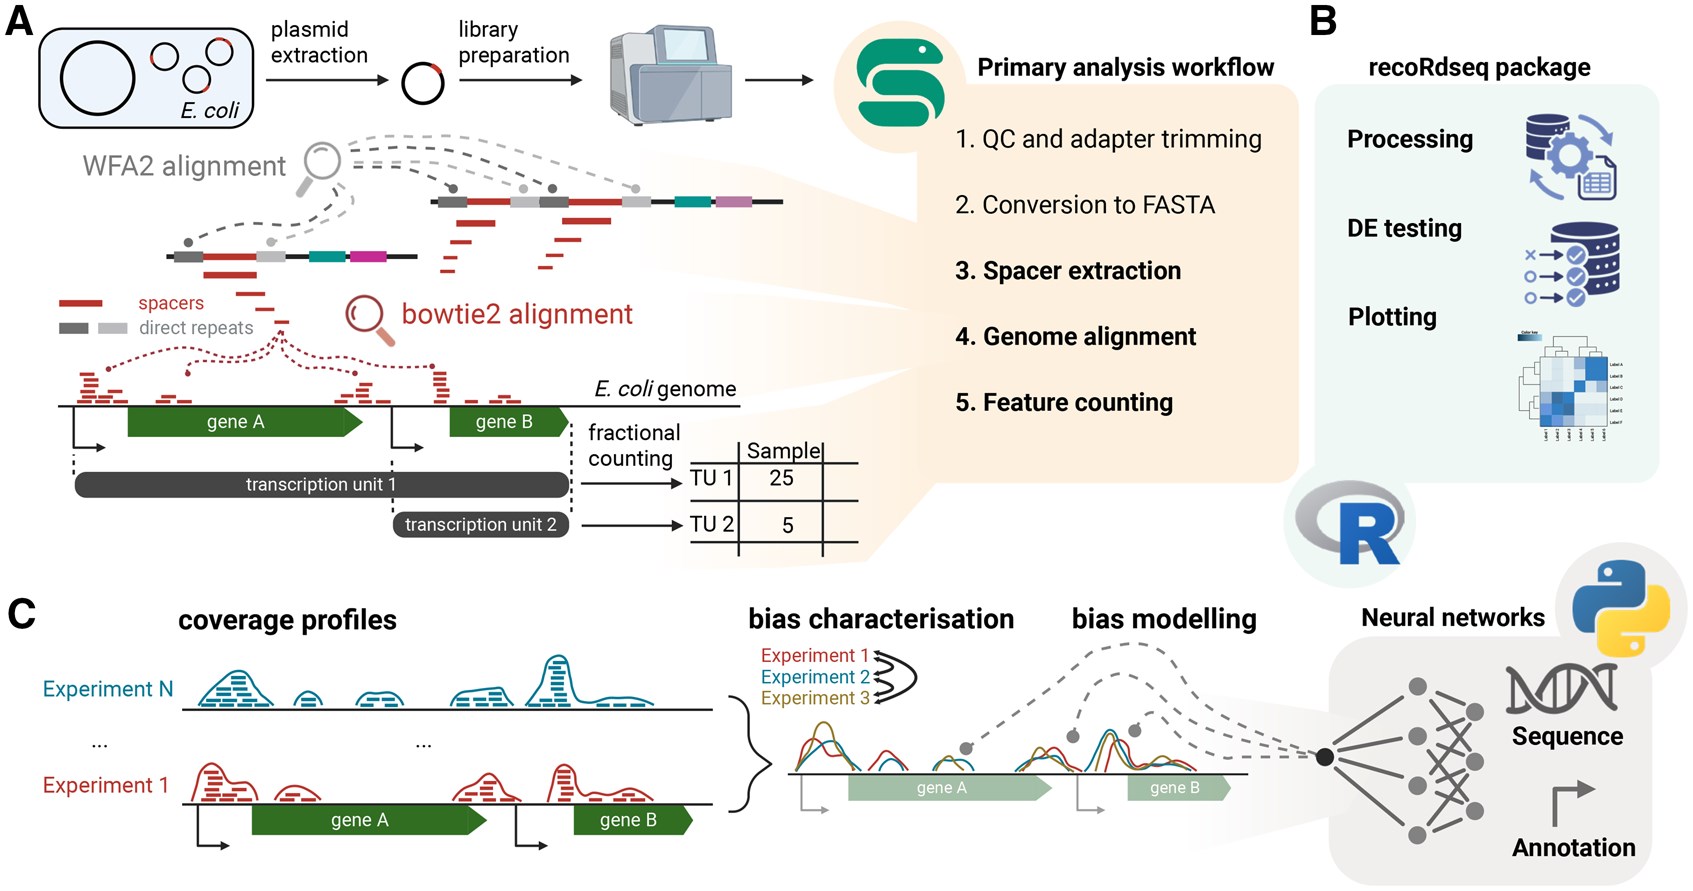
(A) Primary analysis workflow comprising read quality control, adapter trimming, conversion to FASTA, WFA2-based spacer extraction, alignment of spacers to genome references, and transcription unit (TU)-based feature counting. (B) Secondary analysis implemented in the recoRdseq R package, supporting data processing and normalization, differential expression (DE) testing, and visualization of gene- and TU-level results. (C) Characterization and modeling of spacer acquisition biases. Spacers from multiple Record-seq experiments were aligned to the Escherichia coli genome to derive normalized spacer coverage profiles, which were used to train sequence-based neural models that predict acquisition profiles from genomic sequence and annotations.
Recording RNA activity with CRISPR
Record-seq uses engineered Escherichia coli that contain a modified CRISPR system. Inside these cells, fragments derived from RNA are converted into DNA and inserted as short spacer sequences within CRISPR arrays.
These spacers act like a molecular memory. Researchers can later sequence the CRISPR arrays and determine which RNA molecules were present while the bacteria were recording their environment. This makes it possible to capture cumulative transcriptional activity rather than relying on a single snapshot.
The approach has potential applications in areas such as microbiome research, where engineered bacteria could record molecular changes occurring inside environments that are difficult to monitor continuously.
Standard RNA sequencing analysis does not work well
Although Record-seq ultimately measures transcriptional activity, its data differ substantially from conventional RNA sequencing.
RNA-seq generally produces reads sampled directly from RNA molecules throughout a transcript. Record-seq instead measures RNA-derived spacers that were selected by the CRISPR spacer acquisition machinery.
That selection is not uniform. Some regions of transcripts are recorded more frequently than others, particularly untranslated regions and transcript boundaries. Standard RNA-seq analysis methods that focus mainly on gene bodies can therefore discard useful Record-seq signal.
Record-seq datasets can also be sparse, meaning many potential features contain few or no recorded spacers. This creates additional challenges for normalization and statistical analysis.
Making spacer extraction much faster
Before Record-seq data can be analyzed, the short spacer sequences stored within CRISPR arrays must first be identified and extracted from sequencing reads.
This step had previously been a major computational bottleneck.
The new framework uses a wavefront alignment method for rapid sequence matching. According to the researchers, the approach produced an approximately 30-fold increase in processing speed compared with the previous method.
Faster extraction becomes particularly important as experiments grow larger and generate increasing numbers of sequencing reads.
Counting transcription units instead of individual genes
The researchers also changed how Record-seq signal is assigned to biological features.
Traditional RNA-seq analysis often counts reads associated with individual genes. For bacteria, however, several genes can be transcribed together as a single transcription unit.
The new framework therefore supports transcription unit-based counting.
A transcription unit can include genes as well as untranslated regions between or surrounding them. Because Record-seq frequently acquires spacers from these untranslated regions, including them captures information that gene-body counting might otherwise miss.
This approach increased the amount of usable signal and improved statistical power for detecting transcriptional differences.
Improving analysis of sparse transcriptional records
Once spacers have been extracted and counted, researchers still need to compare Record-seq samples.
The new framework includes several normalization approaches designed to account for differences in sequencing depth and spacer counts between samples.
It also introduces a nonparametric method for differential expression testing. Nonparametric statistics make fewer assumptions about how the underlying data are distributed, which can be useful for sparse Record-seq datasets.
The associated recoRdseq software package also provides quality control, differential expression analysis, and visualization tools within a single workflow.
Learning which sequences are most likely to be recorded
Another challenge is that the CRISPR recording machinery does not capture every RNA sequence equally.
To better understand this bias, the researchers examined patterns of spacer acquisition and trained neural network models to predict how likely particular genomic sequences are to be recorded.
These models use DNA sequence and genomic annotations to identify characteristics associated with higher or lower spacer acquisition.
Understanding these preferences is important because a strong Record-seq signal may reflect both biological transcription and the preferences of the recording machinery.
The models also provide a way to investigate whether the same acquisition rules remain valid when Record-seq is adapted to different bacterial species.
Building a complete Record-seq analysis workflow
The new framework brings the major computational steps of Record-seq analysis into a more unified pipeline.
Sequencing reads can be quality controlled, processed to extract CRISPR spacers, aligned to the bacterial genome, assigned to transcription units, normalized, statistically compared, and visualized.
This is important because Record-seq is fundamentally different from standard RNA sequencing. Treating it simply as another RNA-seq dataset can reduce sensitivity or lead to misleading interpretations.
By developing tools around the specific biology of CRISPR-based transcriptional recording, the researchers provide a framework that should make Record-seq data faster to process and easier to interpret.
As transcriptional recording expands into additional microbial systems, improved computational methods could help researchers use engineered cells as biological sensors that preserve information about gene activity over time.
Availability – the the recoRdseq package, and the spacer acquisition modeling frameworkare available at: https://github.com/plattlab/Record-seq-Framework.
Hugi F, Tanna T, Platt RJ. (2026) An end-to-end computational framework for “Record-seq” transcriptional recording data. Bioinformatics 42(Supplement_2): btag479. [article]
Related Posts





RNA sequencing, or RNA-seq, provides a snapshot of which genes are active in a biological sample at the time it is collected. Record-seq takes a different approach. Instead of measuring RNA directly at one moment, it allows engineered bacteria to create a molecular record of their transcriptional activity over time.
A research team from ETH Zurich, Switzerland, have developed a new computational framework specifically for analyzing Record-seq data.
End-to-end Record-seq analysis framework
(A) Primary analysis workflow comprising read quality control, adapter trimming, conversion to FASTA, WFA2-based spacer extraction, alignment of spacers to genome references, and transcription unit (TU)-based feature counting. (B) Secondary analysis implemented in the recoRdseq R package, supporting data processing and normalization, differential expression (DE) testing, and visualization of gene- and TU-level results. (C) Characterization and modeling of spacer acquisition biases. Spacers from multiple Record-seq experiments were aligned to the Escherichia coli genome to derive normalized spacer coverage profiles, which were used to train sequence-based neural models that predict acquisition profiles from genomic sequence and annotations.
Recording RNA activity with CRISPR
Record-seq uses engineered Escherichia coli that contain a modified CRISPR system. Inside these cells, fragments derived from RNA are converted into DNA and inserted as short spacer sequences within CRISPR arrays.
These spacers act like a molecular memory. Researchers can later sequence the CRISPR arrays and determine which RNA molecules were present while the bacteria were recording their environment. This makes it possible to capture cumulative transcriptional activity rather than relying on a single snapshot.
The approach has potential applications in areas such as microbiome research, where engineered bacteria could record molecular changes occurring inside environments that are difficult to monitor continuously.
Standard RNA sequencing analysis does not work well
Although Record-seq ultimately measures transcriptional activity, its data differ substantially from conventional RNA sequencing.
RNA-seq generally produces reads sampled directly from RNA molecules throughout a transcript. Record-seq instead measures RNA-derived spacers that were selected by the CRISPR spacer acquisition machinery.
That selection is not uniform. Some regions of transcripts are recorded more frequently than others, particularly untranslated regions and transcript boundaries. Standard RNA-seq analysis methods that focus mainly on gene bodies can therefore discard useful Record-seq signal.
Record-seq datasets can also be sparse, meaning many potential features contain few or no recorded spacers. This creates additional challenges for normalization and statistical analysis.
Making spacer extraction much faster
Before Record-seq data can be analyzed, the short spacer sequences stored within CRISPR arrays must first be identified and extracted from sequencing reads.
This step had previously been a major computational bottleneck.
The new framework uses a wavefront alignment method for rapid sequence matching. According to the researchers, the approach produced an approximately 30-fold increase in processing speed compared with the previous method.
Faster extraction becomes particularly important as experiments grow larger and generate increasing numbers of sequencing reads.
Counting transcription units instead of individual genes
The researchers also changed how Record-seq signal is assigned to biological features.
Traditional RNA-seq analysis often counts reads associated with individual genes. For bacteria, however, several genes can be transcribed together as a single transcription unit.
The new framework therefore supports transcription unit-based counting.
A transcription unit can include genes as well as untranslated regions between or surrounding them. Because Record-seq frequently acquires spacers from these untranslated regions, including them captures information that gene-body counting might otherwise miss.
This approach increased the amount of usable signal and improved statistical power for detecting transcriptional differences.
Improving analysis of sparse transcriptional records
Once spacers have been extracted and counted, researchers still need to compare Record-seq samples.
The new framework includes several normalization approaches designed to account for differences in sequencing depth and spacer counts between samples.
It also introduces a nonparametric method for differential expression testing. Nonparametric statistics make fewer assumptions about how the underlying data are distributed, which can be useful for sparse Record-seq datasets.
The associated recoRdseq software package also provides quality control, differential expression analysis, and visualization tools within a single workflow.
Learning which sequences are most likely to be recorded
Another challenge is that the CRISPR recording machinery does not capture every RNA sequence equally.
To better understand this bias, the researchers examined patterns of spacer acquisition and trained neural network models to predict how likely particular genomic sequences are to be recorded.
These models use DNA sequence and genomic annotations to identify characteristics associated with higher or lower spacer acquisition.
Understanding these preferences is important because a strong Record-seq signal may reflect both biological transcription and the preferences of the recording machinery.
The models also provide a way to investigate whether the same acquisition rules remain valid when Record-seq is adapted to different bacterial species.
Building a complete Record-seq analysis workflow
The new framework brings the major computational steps of Record-seq analysis into a more unified pipeline.
Sequencing reads can be quality controlled, processed to extract CRISPR spacers, aligned to the bacterial genome, assigned to transcription units, normalized, statistically compared, and visualized.
This is important because Record-seq is fundamentally different from standard RNA sequencing. Treating it simply as another RNA-seq dataset can reduce sensitivity or lead to misleading interpretations.
By developing tools around the specific biology of CRISPR-based transcriptional recording, the researchers provide a framework that should make Record-seq data faster to process and easier to interpret.
As transcriptional recording expands into additional microbial systems, improved computational methods could help researchers use engineered cells as biological sensors that preserve information about gene activity over time.
Availability – the the recoRdseq package, and the spacer acquisition modeling frameworkare available at: https://github.com/plattlab/Record-seq-Framework.
Hugi F, Tanna T, Platt RJ. (2026) An end-to-end computational framework for “Record-seq” transcriptional recording data. Bioinformatics 42(Supplement_2): btag479. [article]
Related Posts
Recent Posts
 Benchmarking RNA sequencing for more accurate alternative splicing analysis
 RNA Sequencing identifies new tick-borne virus that causes flu-like illness
 Eclipsebio expands its RNA characterization capabilities with multi-attribute nanopore-based sequencing assay eSTRAND RNA QC™
 Single-cell RNA sequencing links genetic mutations to cell behavior in cancer
 Small RNA sequencing reveals regulatory roles for sdRNAs in acute myeloid leukemia
 Creative Biolabs expands advanced single-cell multi-omics and RNA sequencing solutions to support biomedical discovery
RNA-Seq Products & Services


Stay Connected