

RNA sequencing, or RNA-seq, allows researchers to measure which parts of a genome are being transcribed into RNA and how strongly those regions are expressed. Being able to predict RNA-seq coverage directly from DNA sequence could help scientists better understand gene regulation and design synthetic DNA that produces more predictable levels of RNA.
A research team from the Department of Computer Science and Artificial Intelligence at Bar-Ilan University in Israel developed ExoShorkie, a machine-learning method designed specifically to predict RNA-seq coverage from exogenous DNA sequences expressed in yeast.
Predicting exogenous gene expression is difficult
Most gene-expression prediction methods are trained using an organism’s native genome. These models learn relationships between DNA sequence and transcription from sequences that have evolved naturally within that organism.
Synthetic biology often introduces exogenous DNA, meaning DNA that comes from another organism or has been artificially designed. These sequences may contain combinations of regulatory signals that differ substantially from those found in the native yeast genome.
As a result, a model trained only on native yeast DNA may not accurately predict how an unfamiliar piece of DNA will be transcribed once it is placed inside a yeast cell.
The researchers developed ExoShorkie to address this problem.
Overview of the ExoShorkie model, its fine-tuning and performance evaluation
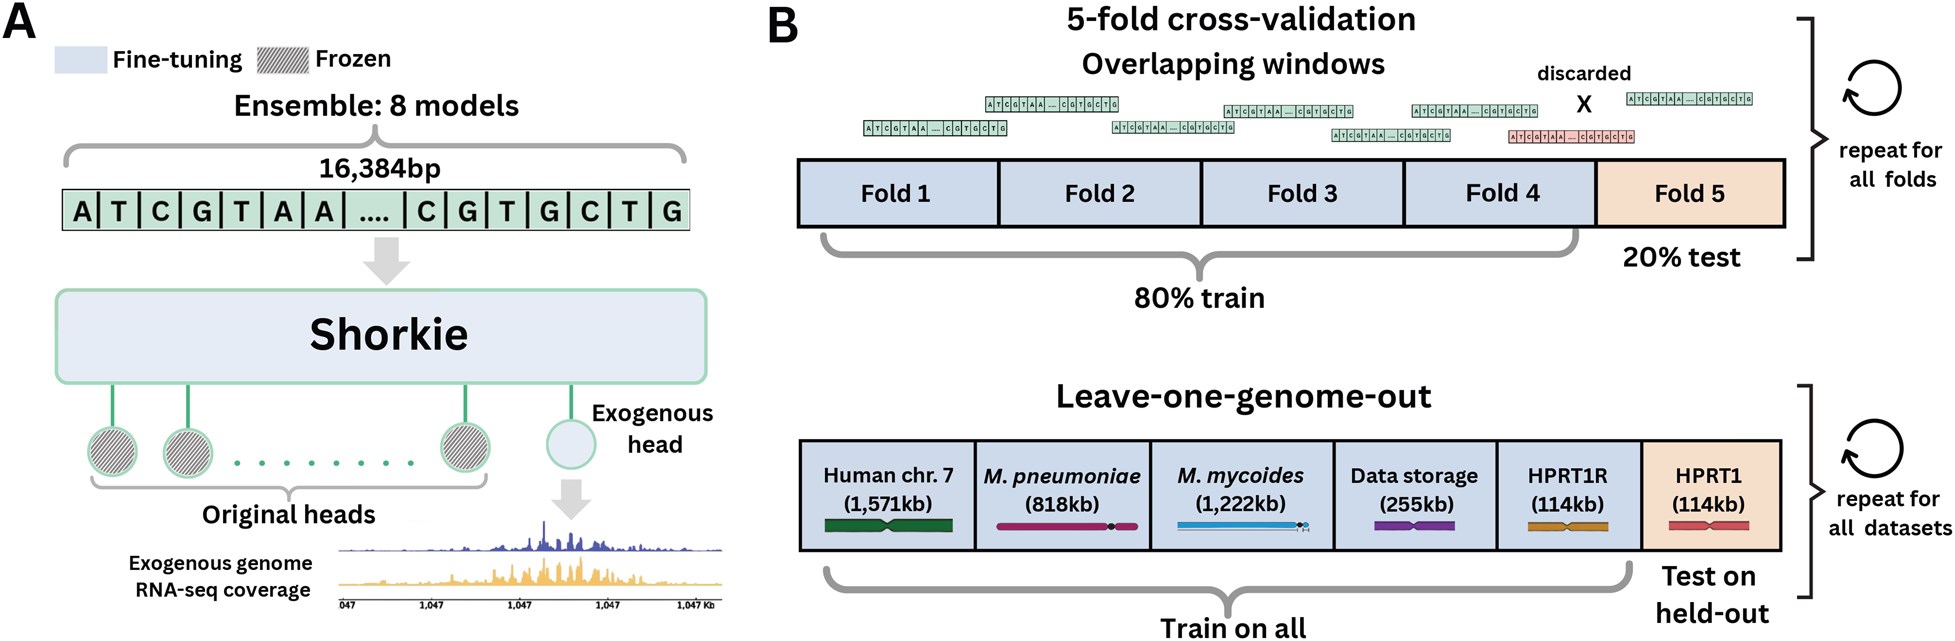
(A) Model fine-tuning scheme. An additional prediction head is added to Shorkie, and both the trunk and the exogenous head are fine-tuned jointly to predict RNA-seq coverage from 16 384 bp-long exogenous DNA sequences expressed in yeast cells, while the original Shorkie prediction heads are frozen. To improve robustness, an ensemble of eight models is trained for each cross-validation split. (B) Evaluation strategies. In 5-fold cross-validation, we partitioned each exogenous genome by genomic coordinates into five folds, with one fold used for testing and four for training. We segmented the sequences into overlapping windows and discarded any windows that overlapped both training and test folds. In addition, we performed a leave-one-genome-out evaluation, in which we held out an entire exogenous genome to assess generalization to unseen exogenous DNA.
Building on an existing RNA-seq prediction model
ExoShorkie extends an earlier model called Shorkie, which was developed to predict RNA-seq coverage from DNA sequences in yeast.
Rather than training an entirely new model from the beginning, the researchers used transfer learning. This approach allows a machine-learning model to begin with information learned from one dataset and then adapt that knowledge using a different set of data.
For ExoShorkie, the model was trained across multiple RNA-seq datasets containing large exogenous genomes expressed in yeast. This allowed it to learn how unfamiliar DNA sequences behave within the yeast transcriptional environment.
Predicting RNA sequencing coverage more accurately
The researchers tested whether ExoShorkie could predict RNA-seq coverage for exogenous genomes that were not included during training.
ExoShorkie performed better than a version of Shorkie trained only on the native yeast genome. It also outperformed Yorzoi, another method capable of predicting RNA-seq coverage from exogenous sequences in yeast.
The model maintained its performance in both cross-validation and leave-one-genome-out testing, where an entire genome was withheld during training and then used to evaluate how well the model handled unfamiliar sequence data.
This type of testing is important for synthetic biology because researchers often want to predict the behavior of DNA sequences that differ substantially from anything previously measured.
Learning which DNA sequences regulate transcription
ExoShorkie was designed not only to generate predictions, but also to help researchers understand why those predictions are made.
By examining what the model learned, the researchers identified DNA sequence motifs associated with transcriptional regulation. Their analysis also suggested that some regulatory rules differ between native yeast DNA and exogenous sequences.
These differences could help explain why models trained exclusively on native genomes sometimes struggle when applied to synthetic or foreign DNA.
Machine-learning interpretability can therefore provide two benefits. It can improve prediction while also revealing biological features that may influence how cells recognize and transcribe unfamiliar genetic sequences.
Supporting synthetic biology design
Predicting gene expression from DNA sequence could become particularly useful when researchers design large synthetic DNA constructs containing multiple genes.
Synthetic biologists often need each gene within a construct to be expressed at an appropriate level. If expression is too high or too low, the engineered biological system may not behave as intended.
ExoShorkie provides a framework for estimating RNA-seq coverage before a construct is experimentally tested. The authors suggest that the approach could eventually support sequence optimization, allowing researchers to design long synthetic DNA constructs with more predictable expression levels.
Connecting RNA sequencing with machine learning
RNA sequencing provides experimental measurements of transcription, while machine learning can use those measurements to discover patterns connecting DNA sequence with gene expression.
ExoShorkie demonstrates how RNA-seq datasets from exogenous genomes can be used to train models that generalize beyond native genomic sequences. This is particularly relevant to synthetic biology, where researchers routinely introduce new combinations of DNA into cells.
By improving RNA-seq coverage prediction and revealing regulatory patterns within exogenous DNA, ExoShorkie could help researchers better understand how yeast responds to unfamiliar genetic sequences and support the design of more predictable engineered biological systems.
Availability: ExoShorkie is available at https://github.com/OrensteinLab/ExoShorkie.
Mandl J, Orenstein Y. (2026) ExoShorkie: predicting RNA-seq coverage of exogenous genomes in yeast by transfer learning. Bioinformatics 42(Supplement_2): btag369. [article]
Related Posts





RNA sequencing, or RNA-seq, allows researchers to measure which parts of a genome are being transcribed into RNA and how strongly those regions are expressed. Being able to predict RNA-seq coverage directly from DNA sequence could help scientists better understand gene regulation and design synthetic DNA that produces more predictable levels of RNA.
A research team from the Department of Computer Science and Artificial Intelligence at Bar-Ilan University in Israel developed ExoShorkie, a machine-learning method designed specifically to predict RNA-seq coverage from exogenous DNA sequences expressed in yeast.
Predicting exogenous gene expression is difficult
Most gene-expression prediction methods are trained using an organism’s native genome. These models learn relationships between DNA sequence and transcription from sequences that have evolved naturally within that organism.
Synthetic biology often introduces exogenous DNA, meaning DNA that comes from another organism or has been artificially designed. These sequences may contain combinations of regulatory signals that differ substantially from those found in the native yeast genome.
As a result, a model trained only on native yeast DNA may not accurately predict how an unfamiliar piece of DNA will be transcribed once it is placed inside a yeast cell.
The researchers developed ExoShorkie to address this problem.
Overview of the ExoShorkie model, its fine-tuning and performance evaluation
(A) Model fine-tuning scheme. An additional prediction head is added to Shorkie, and both the trunk and the exogenous head are fine-tuned jointly to predict RNA-seq coverage from 16 384 bp-long exogenous DNA sequences expressed in yeast cells, while the original Shorkie prediction heads are frozen. To improve robustness, an ensemble of eight models is trained for each cross-validation split. (B) Evaluation strategies. In 5-fold cross-validation, we partitioned each exogenous genome by genomic coordinates into five folds, with one fold used for testing and four for training. We segmented the sequences into overlapping windows and discarded any windows that overlapped both training and test folds. In addition, we performed a leave-one-genome-out evaluation, in which we held out an entire exogenous genome to assess generalization to unseen exogenous DNA.
Building on an existing RNA-seq prediction model
ExoShorkie extends an earlier model called Shorkie, which was developed to predict RNA-seq coverage from DNA sequences in yeast.
Rather than training an entirely new model from the beginning, the researchers used transfer learning. This approach allows a machine-learning model to begin with information learned from one dataset and then adapt that knowledge using a different set of data.
For ExoShorkie, the model was trained across multiple RNA-seq datasets containing large exogenous genomes expressed in yeast. This allowed it to learn how unfamiliar DNA sequences behave within the yeast transcriptional environment.
Predicting RNA sequencing coverage more accurately
The researchers tested whether ExoShorkie could predict RNA-seq coverage for exogenous genomes that were not included during training.
ExoShorkie performed better than a version of Shorkie trained only on the native yeast genome. It also outperformed Yorzoi, another method capable of predicting RNA-seq coverage from exogenous sequences in yeast.
The model maintained its performance in both cross-validation and leave-one-genome-out testing, where an entire genome was withheld during training and then used to evaluate how well the model handled unfamiliar sequence data.
This type of testing is important for synthetic biology because researchers often want to predict the behavior of DNA sequences that differ substantially from anything previously measured.
Learning which DNA sequences regulate transcription
ExoShorkie was designed not only to generate predictions, but also to help researchers understand why those predictions are made.
By examining what the model learned, the researchers identified DNA sequence motifs associated with transcriptional regulation. Their analysis also suggested that some regulatory rules differ between native yeast DNA and exogenous sequences.
These differences could help explain why models trained exclusively on native genomes sometimes struggle when applied to synthetic or foreign DNA.
Machine-learning interpretability can therefore provide two benefits. It can improve prediction while also revealing biological features that may influence how cells recognize and transcribe unfamiliar genetic sequences.
Supporting synthetic biology design
Predicting gene expression from DNA sequence could become particularly useful when researchers design large synthetic DNA constructs containing multiple genes.
Synthetic biologists often need each gene within a construct to be expressed at an appropriate level. If expression is too high or too low, the engineered biological system may not behave as intended.
ExoShorkie provides a framework for estimating RNA-seq coverage before a construct is experimentally tested. The authors suggest that the approach could eventually support sequence optimization, allowing researchers to design long synthetic DNA constructs with more predictable expression levels.
Connecting RNA sequencing with machine learning
RNA sequencing provides experimental measurements of transcription, while machine learning can use those measurements to discover patterns connecting DNA sequence with gene expression.
ExoShorkie demonstrates how RNA-seq datasets from exogenous genomes can be used to train models that generalize beyond native genomic sequences. This is particularly relevant to synthetic biology, where researchers routinely introduce new combinations of DNA into cells.
By improving RNA-seq coverage prediction and revealing regulatory patterns within exogenous DNA, ExoShorkie could help researchers better understand how yeast responds to unfamiliar genetic sequences and support the design of more predictable engineered biological systems.
Availability: ExoShorkie is available at https://github.com/OrensteinLab/ExoShorkie.
Mandl J, Orenstein Y. (2026) ExoShorkie: predicting RNA-seq coverage of exogenous genomes in yeast by transfer learning. Bioinformatics 42(Supplement_2): btag369. [article]
Related Posts
Recent Posts
 Benchmarking RNA sequencing for more accurate alternative splicing analysis
 RNA Sequencing identifies new tick-borne virus that causes flu-like illness
 Eclipsebio expands its RNA characterization capabilities with multi-attribute nanopore-based sequencing assay eSTRAND RNA QC™
 Single-cell RNA sequencing links genetic mutations to cell behavior in cancer
 Small RNA sequencing reveals regulatory roles for sdRNAs in acute myeloid leukemia
 Creative Biolabs expands advanced single-cell multi-omics and RNA sequencing solutions to support biomedical discovery
RNA-Seq Products & Services


Stay Connected