


Small RNAs have become increasingly important in biomarker research because they can provide information about disease status using relatively accessible samples such as blood, urine, plasma, and extracellular vesicles. Among these molecules, microRNAs (miRNAs) are especially well known because they help regulate gene expression and have been linked to many diseases.
Researchers often use small RNA sequencing (small RNA-seq) to study these molecules because it allows an untargeted analysis of the entire small RNAome, not just miRNAs. This means scientists can investigate many RNA types simultaneously, including tRNAs, piRNAs, snRNAs, and snoRNAs.
However, analyzing small RNA sequencing data can be challenging. Different laboratories often report quality metrics differently, making it difficult to compare studies and establish consistent standards.
Researchers at TAmiRNA GmbH have developed a new workflow called miND, short for miRNA NGS Discovery pipeline, to help address this problem.
The miND pipeline aims to simplify analysis by connecting laboratory scientists with bioinformatics workflows through an easier setup process and automated reporting.
Flowchart representing the high-level steps of data processing through the pipeline
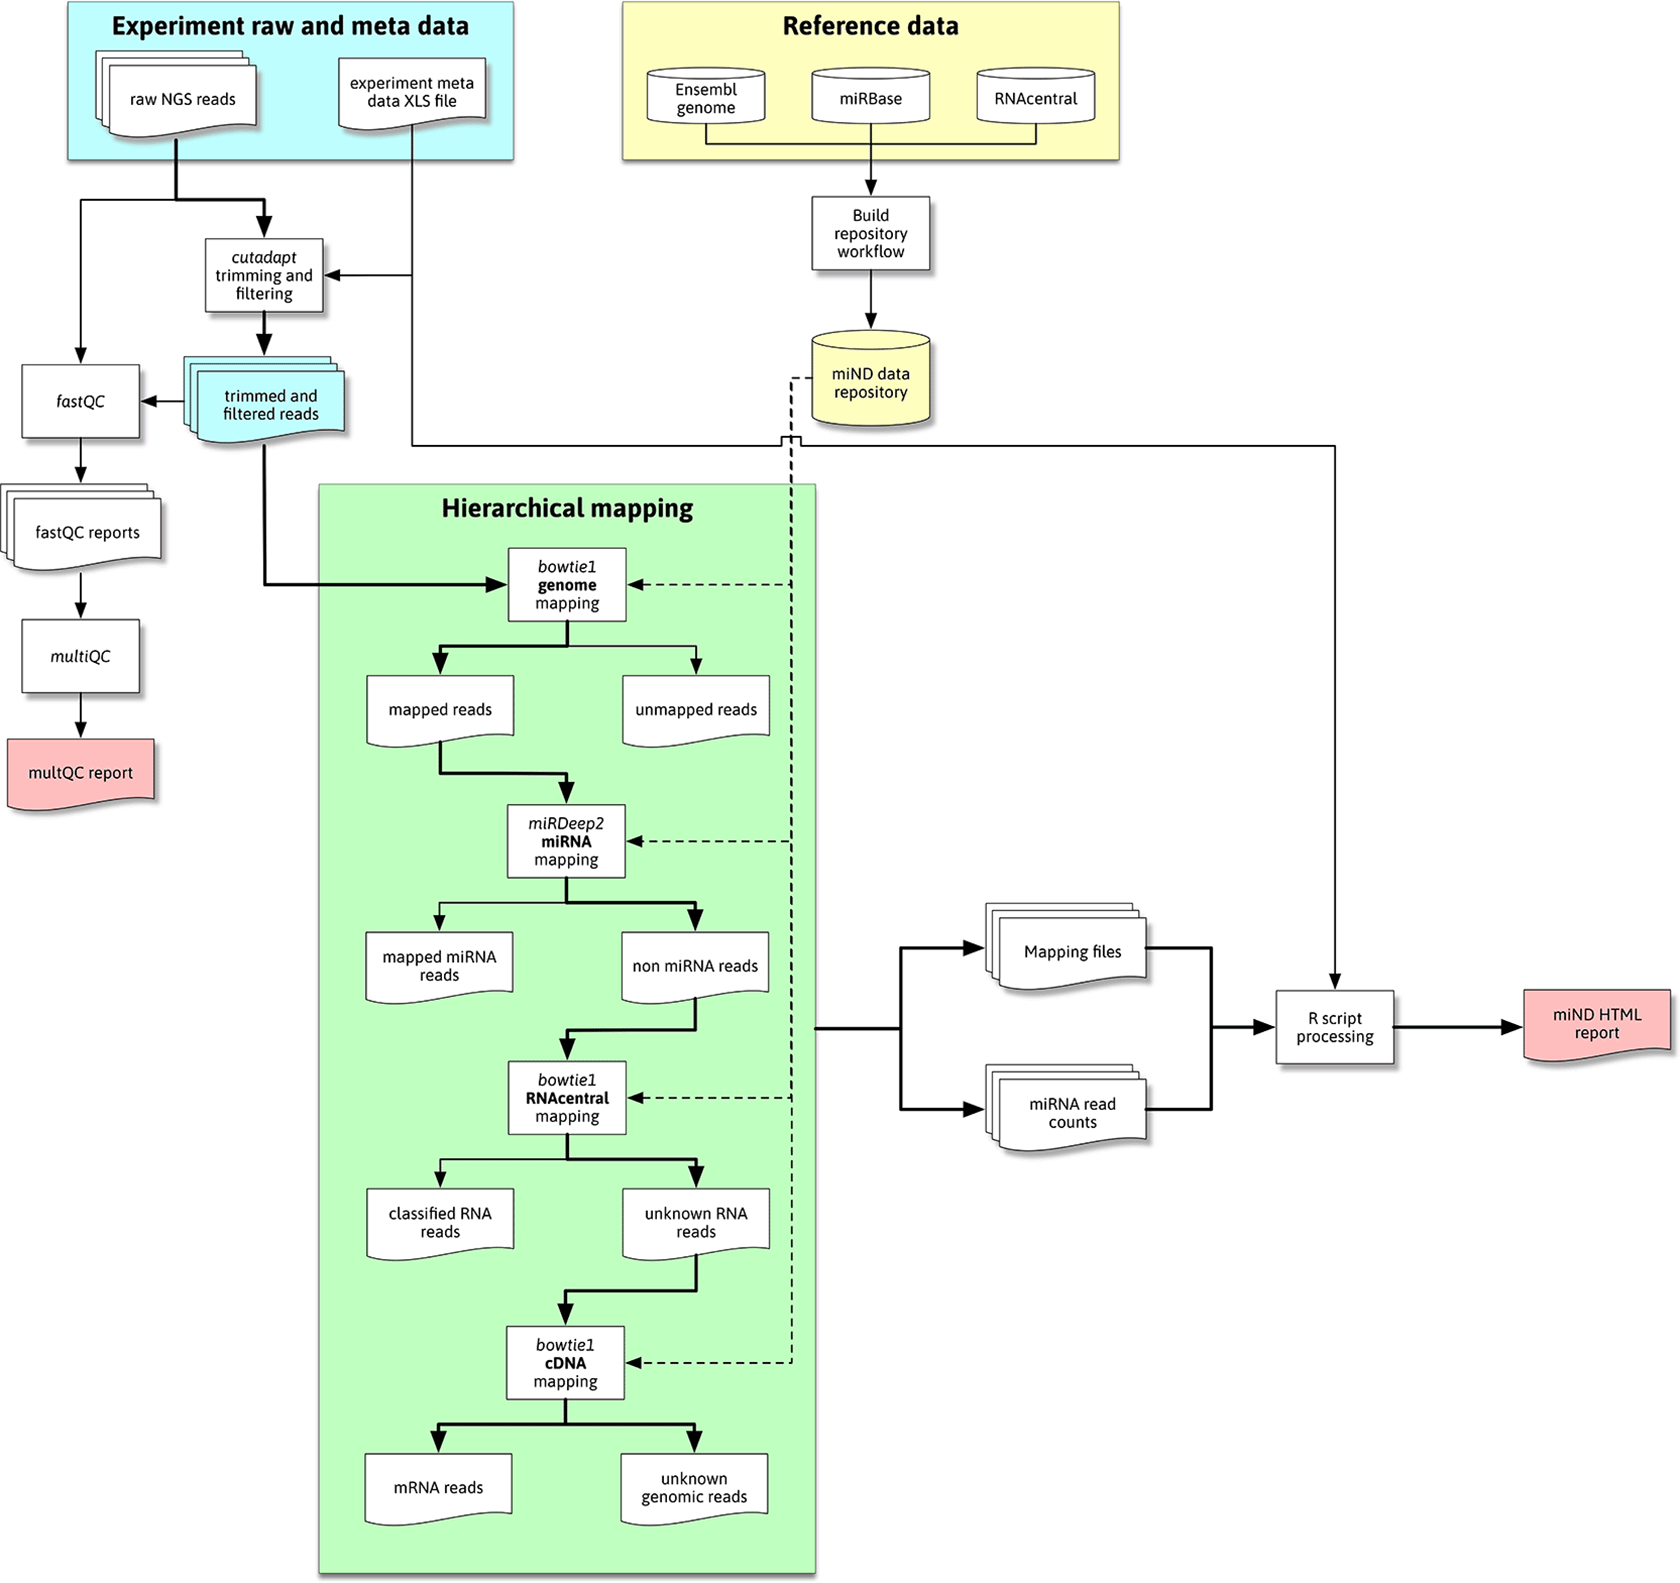
Reference data is downloaded and processed by the repository build process (yellow area; top right) and then available for the miND pipeline in the repository/subfolder. Raw next-generations sequencing (NGS) data (blue area) is first adapter and quality trimmed and then handled by quality control (QC) tools and processed through hierarchical mapping steps (green area). These steps produce a set of mapping files that are then ingested and analyzed by R scripts, producing the miND report in the end.
If sample group information is available, miND can also automatically perform differential expression analysis to identify RNAs that differ between biological conditions.
Although the pipeline focuses on miRNAs, it also analyzes several additional RNA classes, including:
- tRNAs
- piRNAs
- snRNAs
- snoRNAs
Importantly, mapping statistics are generated for all RNA categories, enabling further downstream analysis.
The authors designed miND using Snakemake, a flexible workflow management system widely used in bioinformatics. Reference databases are downloaded and prepared through a separate workflow, allowing researchers to update databases while maintaining reproducibility.
The pipeline has already been tested across many sample types and biological sources, including tissues, plasma, urine, and extracellular vesicles.
Because extracellular vesicles are increasingly explored as liquid biopsy biomarkers, standardized workflows for RNA sequencing analysis may become increasingly important.
By automating analysis and generating comprehensive reports, miND may help improve reproducibility and simplify small RNA biomarker discovery studies.
Availability – Source code available from: https://github.com/tamirna/miND
Diendorfer A, Khamina K, Pultar M, Hackl M. (2026) miND (miRNA NGS Discovery pipeline): a small RNA-seq analysis pipeline and report generator for microRNA biomarker discovery studies. F1000Research 11: 233. [article]
Related Posts






Small RNAs have become increasingly important in biomarker research because they can provide information about disease status using relatively accessible samples such as blood, urine, plasma, and extracellular vesicles. Among these molecules, microRNAs (miRNAs) are especially well known because they help regulate gene expression and have been linked to many diseases.
Researchers often use small RNA sequencing (small RNA-seq) to study these molecules because it allows an untargeted analysis of the entire small RNAome, not just miRNAs. This means scientists can investigate many RNA types simultaneously, including tRNAs, piRNAs, snRNAs, and snoRNAs.
However, analyzing small RNA sequencing data can be challenging. Different laboratories often report quality metrics differently, making it difficult to compare studies and establish consistent standards.
Researchers at TAmiRNA GmbH have developed a new workflow called miND, short for miRNA NGS Discovery pipeline, to help address this problem.
The miND pipeline aims to simplify analysis by connecting laboratory scientists with bioinformatics workflows through an easier setup process and automated reporting.
Flowchart representing the high-level steps of data processing through the pipeline
Reference data is downloaded and processed by the repository build process (yellow area; top right) and then available for the miND pipeline in the repository/subfolder. Raw next-generations sequencing (NGS) data (blue area) is first adapter and quality trimmed and then handled by quality control (QC) tools and processed through hierarchical mapping steps (green area). These steps produce a set of mapping files that are then ingested and analyzed by R scripts, producing the miND report in the end.
If sample group information is available, miND can also automatically perform differential expression analysis to identify RNAs that differ between biological conditions.
Although the pipeline focuses on miRNAs, it also analyzes several additional RNA classes, including:
- tRNAs
- piRNAs
- snRNAs
- snoRNAs
Importantly, mapping statistics are generated for all RNA categories, enabling further downstream analysis.
The authors designed miND using Snakemake, a flexible workflow management system widely used in bioinformatics. Reference databases are downloaded and prepared through a separate workflow, allowing researchers to update databases while maintaining reproducibility.
The pipeline has already been tested across many sample types and biological sources, including tissues, plasma, urine, and extracellular vesicles.
Because extracellular vesicles are increasingly explored as liquid biopsy biomarkers, standardized workflows for RNA sequencing analysis may become increasingly important.
By automating analysis and generating comprehensive reports, miND may help improve reproducibility and simplify small RNA biomarker discovery studies.
Availability – Source code available from: https://github.com/tamirna/miND
Diendorfer A, Khamina K, Pultar M, Hackl M. (2026) miND (miRNA NGS Discovery pipeline): a small RNA-seq analysis pipeline and report generator for microRNA biomarker discovery studies. F1000Research 11: 233. [article]
Related Posts
Recent Posts
 Benchmarking RNA sequencing for more accurate alternative splicing analysis
 RNA Sequencing identifies new tick-borne virus that causes flu-like illness
 Eclipsebio expands its RNA characterization capabilities with multi-attribute nanopore-based sequencing assay eSTRAND RNA QC™
 Single-cell RNA sequencing links genetic mutations to cell behavior in cancer
 Small RNA sequencing reveals regulatory roles for sdRNAs in acute myeloid leukemia
 Creative Biolabs expands advanced single-cell multi-omics and RNA sequencing solutions to support biomedical discovery
RNA-Seq Products & Services


Stay Connected