

RNA sequencing has made it possible to study the activity of individual cells, revealing that even cells of the same type can behave very differently. By combining RNA sequencing with other types of molecular data, researchers have created detailed cell atlases that help scientists better understand healthy tissues and disease. As these atlases continue to grow, however, updating them has become increasingly difficult because new datasets typically require all of the existing data to be processed again.
Researchers from the Beijing Institute of Basic Medical Sciences have developed a new computational framework called MIRACLE that allows these atlases to be updated continuously without starting the entire integration process from scratch.
MIRACLE, short for Multimodal Integration with Continual Learning, uses artificial intelligence to incorporate newly generated datasets as they become available while preserving information learned from previous data. This approach greatly reduces the time and computing resources required to maintain large biological reference atlases.
Overview of the MIRACLE framework for continual multimodal integration
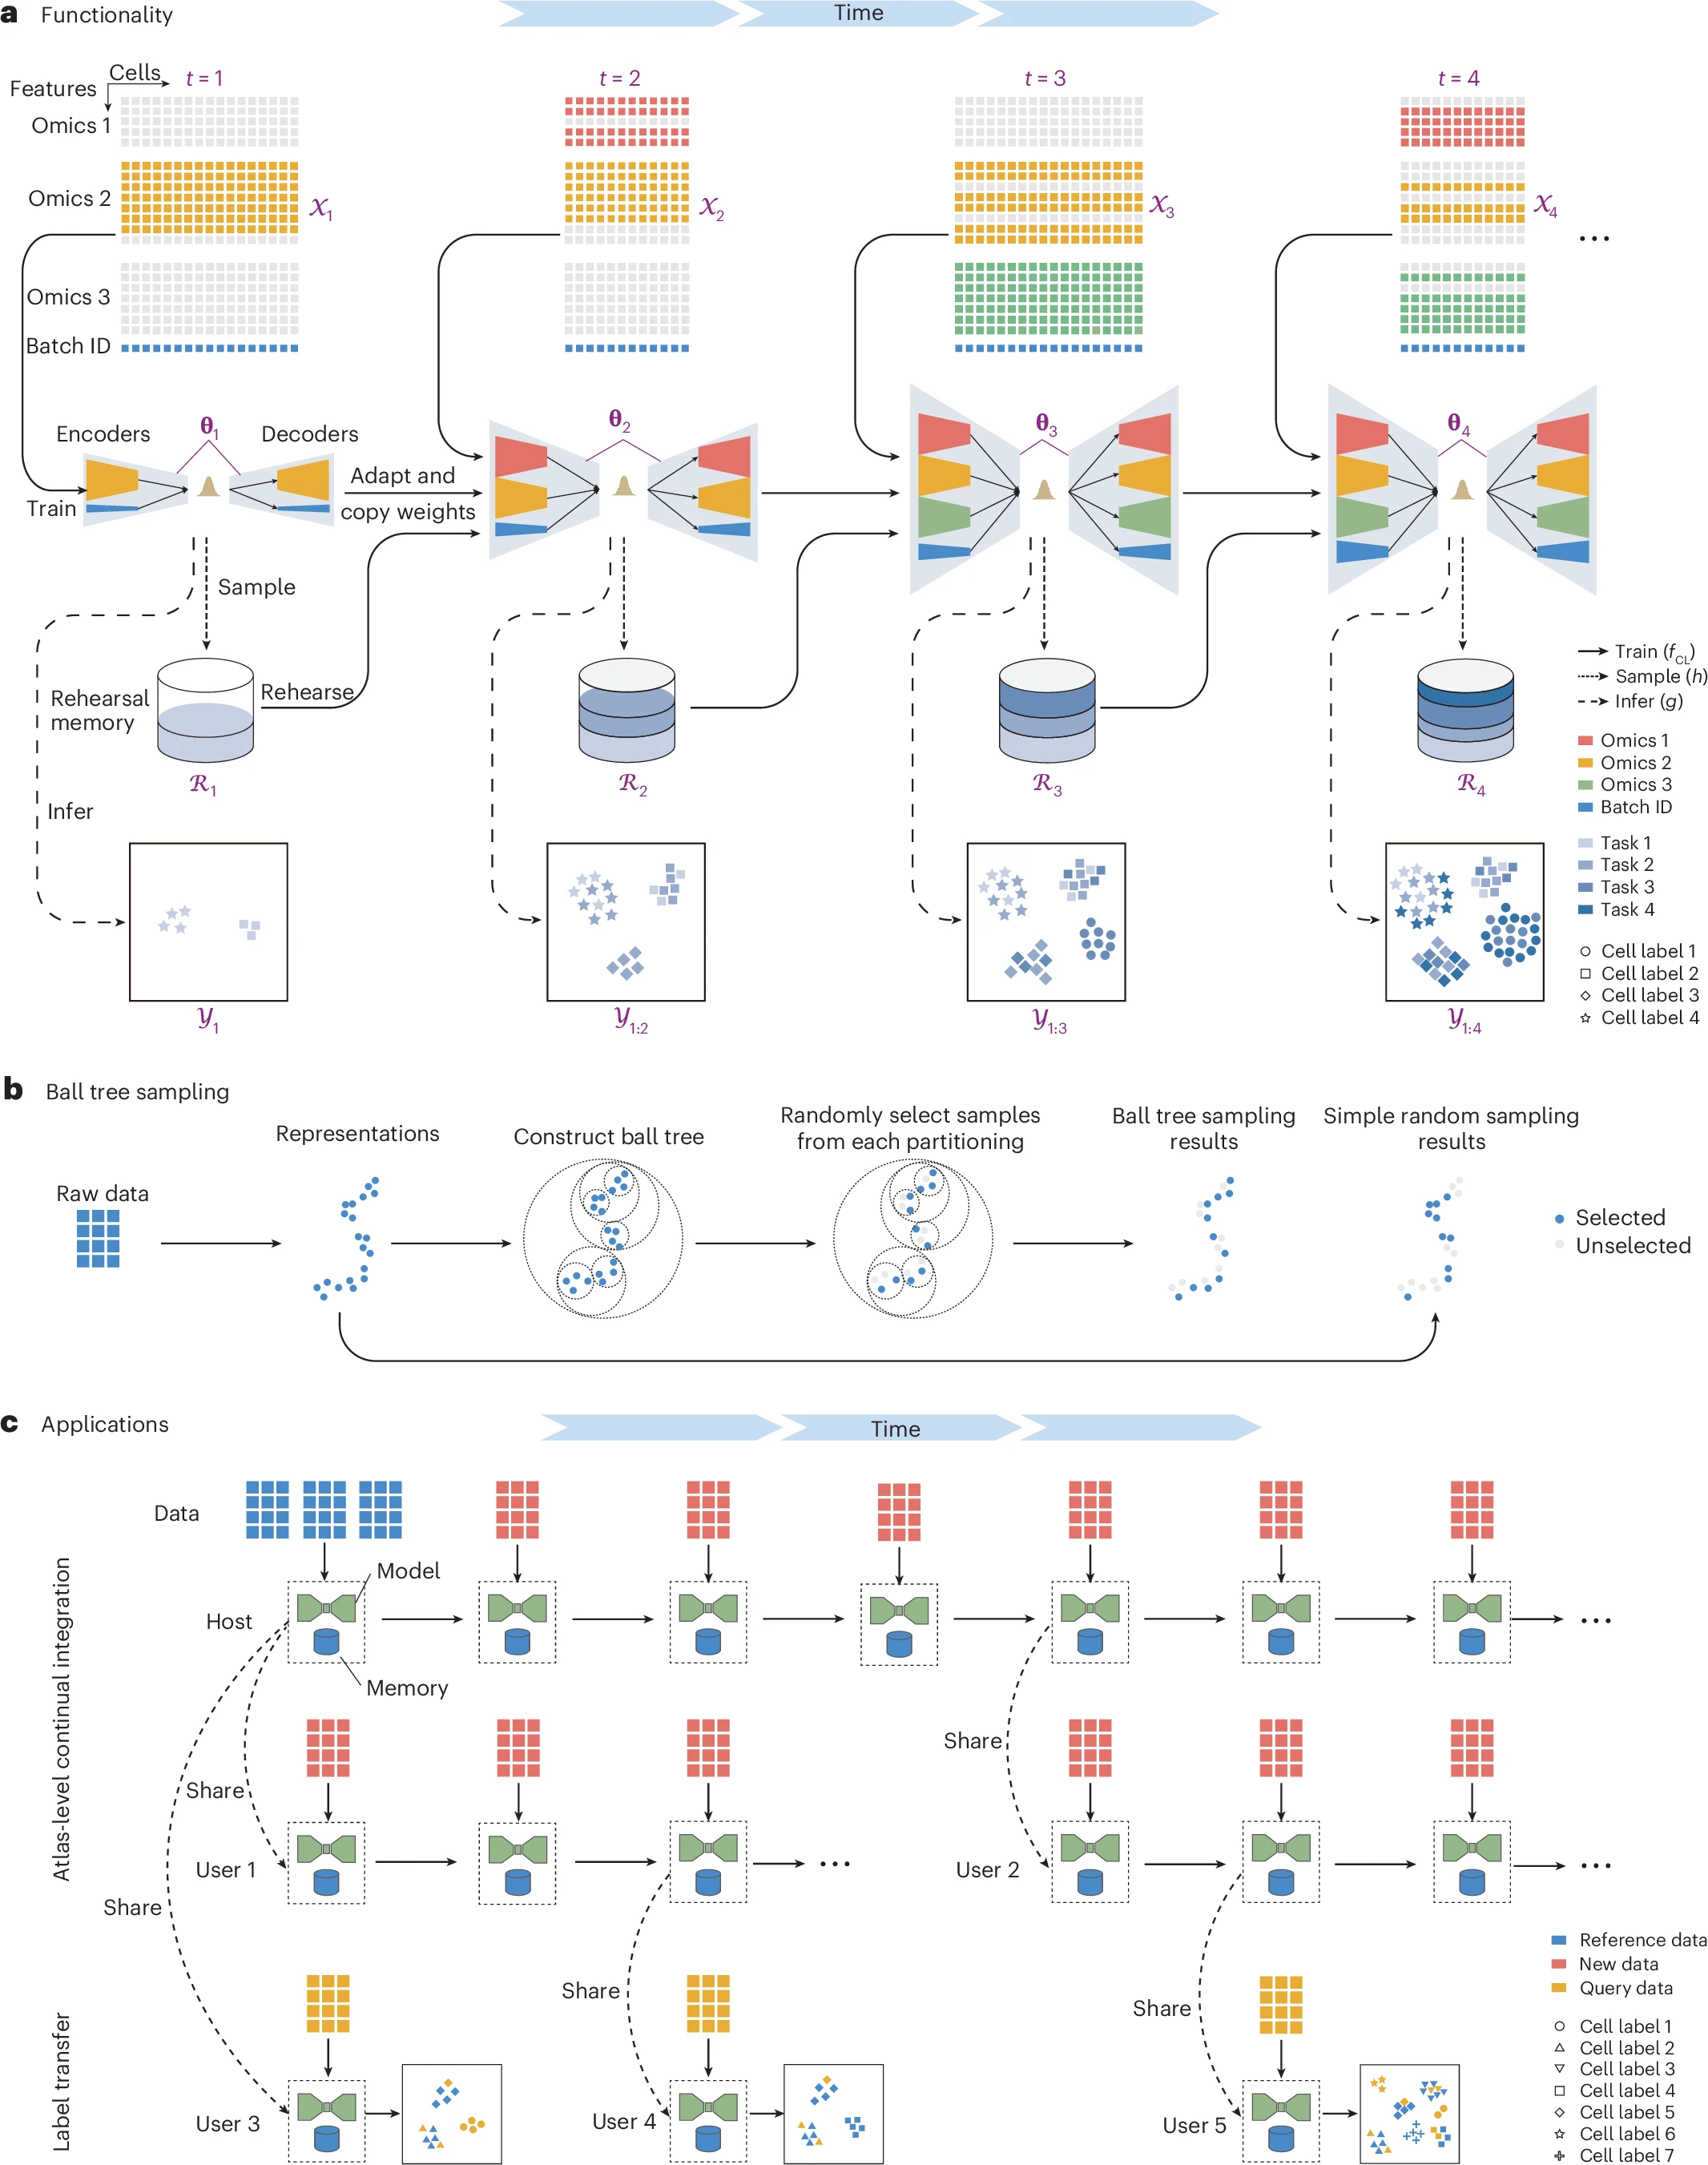
a, At time t = 1, a model is trained on data using function fCL, generating integration results via inference function g. Rehearsal memory is then created using sampling function h. For t > 1, new data is integrated by updating the previous model θt−1 to obtain the new model θt via fCL. The inference function g produces integration results for all data observed up to time t, and rehearsal memory is updated from to . b, BTS partitions the embedding space with a ball tree and draws samples from each partition, better preserving the data distribution than simple random sampling. c, To achieve atlas-level continual integration, a host can begin by building a model using reference data and then continuously incorporate new data into this model. Users can also continuously update the model with their own data and reshare it, or use the model to perform label transfer on their data.
Traditional data integration methods work well when all datasets are available at once. However, as new RNA sequencing, protein, or chromatin accessibility datasets are generated, researchers often need to repeat the entire integration process. This becomes increasingly impractical as the amount of data continues to grow.
To solve this problem, MIRACLE uses two important strategies. First, it adapts its internal architecture as new data are introduced. Second, it periodically reviews representative information from earlier datasets, allowing the system to retain previously learned biological relationships while incorporating new knowledge.
The researchers evaluated MIRACLE using a variety of multimodal datasets collected from different tissues, diseases, and experimental platforms. The framework accurately integrated new datasets while maintaining the biological relationships already present in existing atlases. Compared with conventional approaches, MIRACLE completed these updates much more efficiently.
The team also applied MIRACLE to datasets from respiratory diseases, including COVID-19, influenza A, and tuberculosis. By integrating information from multiple molecular data types, the framework identified both shared immune responses and disease-specific cellular mechanisms that distinguish these infections.
As RNA sequencing technologies continue to generate larger and more diverse datasets, scalable computational tools will become increasingly important. Frameworks such as MIRACLE allow biological atlases to evolve continuously rather than requiring complete reconstruction every time new information becomes available.
By making it easier to integrate new multimodal datasets, MIRACLE could accelerate biological discovery, improve collaboration among research groups, and help scientists build increasingly comprehensive references for studying human health and disease.
Availability – MIRACLE is available via GitHub at https://github.com/sc-miracle/miracle and via Zenodo at https://doi.org/10.5281/zenodo.20744271
Zhou J, Wang J, Hu S, Kan T, Feng C, Qiang X, Dong G, Shi J, Liu R, Bo X, Ou-Yang L, Ying X, He Z. (2026) Continual integration of single-cell multimodal data with MIRACLE. Nature Computational Science [Epub ahead of print]. [article]
Related Posts






RNA sequencing has made it possible to study the activity of individual cells, revealing that even cells of the same type can behave very differently. By combining RNA sequencing with other types of molecular data, researchers have created detailed cell atlases that help scientists better understand healthy tissues and disease. As these atlases continue to grow, however, updating them has become increasingly difficult because new datasets typically require all of the existing data to be processed again.
Researchers from the Beijing Institute of Basic Medical Sciences have developed a new computational framework called MIRACLE that allows these atlases to be updated continuously without starting the entire integration process from scratch.
MIRACLE, short for Multimodal Integration with Continual Learning, uses artificial intelligence to incorporate newly generated datasets as they become available while preserving information learned from previous data. This approach greatly reduces the time and computing resources required to maintain large biological reference atlases.
Overview of the MIRACLE framework for continual multimodal integration
a, At time t = 1, a model is trained on data using function fCL, generating integration results via inference function g. Rehearsal memory is then created using sampling function h. For t > 1, new data is integrated by updating the previous model θt−1 to obtain the new model θt via fCL. The inference function g produces integration results for all data observed up to time t, and rehearsal memory is updated from to . b, BTS partitions the embedding space with a ball tree and draws samples from each partition, better preserving the data distribution than simple random sampling. c, To achieve atlas-level continual integration, a host can begin by building a model using reference data and then continuously incorporate new data into this model. Users can also continuously update the model with their own data and reshare it, or use the model to perform label transfer on their data.
Traditional data integration methods work well when all datasets are available at once. However, as new RNA sequencing, protein, or chromatin accessibility datasets are generated, researchers often need to repeat the entire integration process. This becomes increasingly impractical as the amount of data continues to grow.
To solve this problem, MIRACLE uses two important strategies. First, it adapts its internal architecture as new data are introduced. Second, it periodically reviews representative information from earlier datasets, allowing the system to retain previously learned biological relationships while incorporating new knowledge.
The researchers evaluated MIRACLE using a variety of multimodal datasets collected from different tissues, diseases, and experimental platforms. The framework accurately integrated new datasets while maintaining the biological relationships already present in existing atlases. Compared with conventional approaches, MIRACLE completed these updates much more efficiently.
The team also applied MIRACLE to datasets from respiratory diseases, including COVID-19, influenza A, and tuberculosis. By integrating information from multiple molecular data types, the framework identified both shared immune responses and disease-specific cellular mechanisms that distinguish these infections.
As RNA sequencing technologies continue to generate larger and more diverse datasets, scalable computational tools will become increasingly important. Frameworks such as MIRACLE allow biological atlases to evolve continuously rather than requiring complete reconstruction every time new information becomes available.
By making it easier to integrate new multimodal datasets, MIRACLE could accelerate biological discovery, improve collaboration among research groups, and help scientists build increasingly comprehensive references for studying human health and disease.
Availability – MIRACLE is available via GitHub at https://github.com/sc-miracle/miracle and via Zenodo at https://doi.org/10.5281/zenodo.20744271
Zhou J, Wang J, Hu S, Kan T, Feng C, Qiang X, Dong G, Shi J, Liu R, Bo X, Ou-Yang L, Ying X, He Z. (2026) Continual integration of single-cell multimodal data with MIRACLE. Nature Computational Science [Epub ahead of print]. [article]
Related Posts
Recent Posts
 Benchmarking RNA sequencing for more accurate alternative splicing analysis
 RNA Sequencing identifies new tick-borne virus that causes flu-like illness
 Eclipsebio expands its RNA characterization capabilities with multi-attribute nanopore-based sequencing assay eSTRAND RNA QC™
 Single-cell RNA sequencing links genetic mutations to cell behavior in cancer
 Small RNA sequencing reveals regulatory roles for sdRNAs in acute myeloid leukemia
 Creative Biolabs expands advanced single-cell multi-omics and RNA sequencing solutions to support biomedical discovery
RNA-Seq Products & Services


Stay Connected