

Single-cell RNA sequencing has made it possible to measure gene activity in millions of individual cells. Large projects such as the Human Cell Atlas are using these technologies to build detailed maps of healthy and diseased tissues.
However, most RNA sequencing analysis pipelines convert raw sequencing data into gene or transcript counts. This makes the data easier to analyze, but much of the original sequence-level information is no longer readily searchable. Researchers who want to look for a particular mutation, splice junction, pathogen sequence, or previously uncharacterized RNA may need to download and reprocess enormous amounts of raw data.
Researchers from the Max Delbrück Center for Molecular Medicine, Germany have now developed a computational platform called Malva to make this sequence information directly searchable.
Malva enables instantaneous sequence-based queries across single-cell atlases
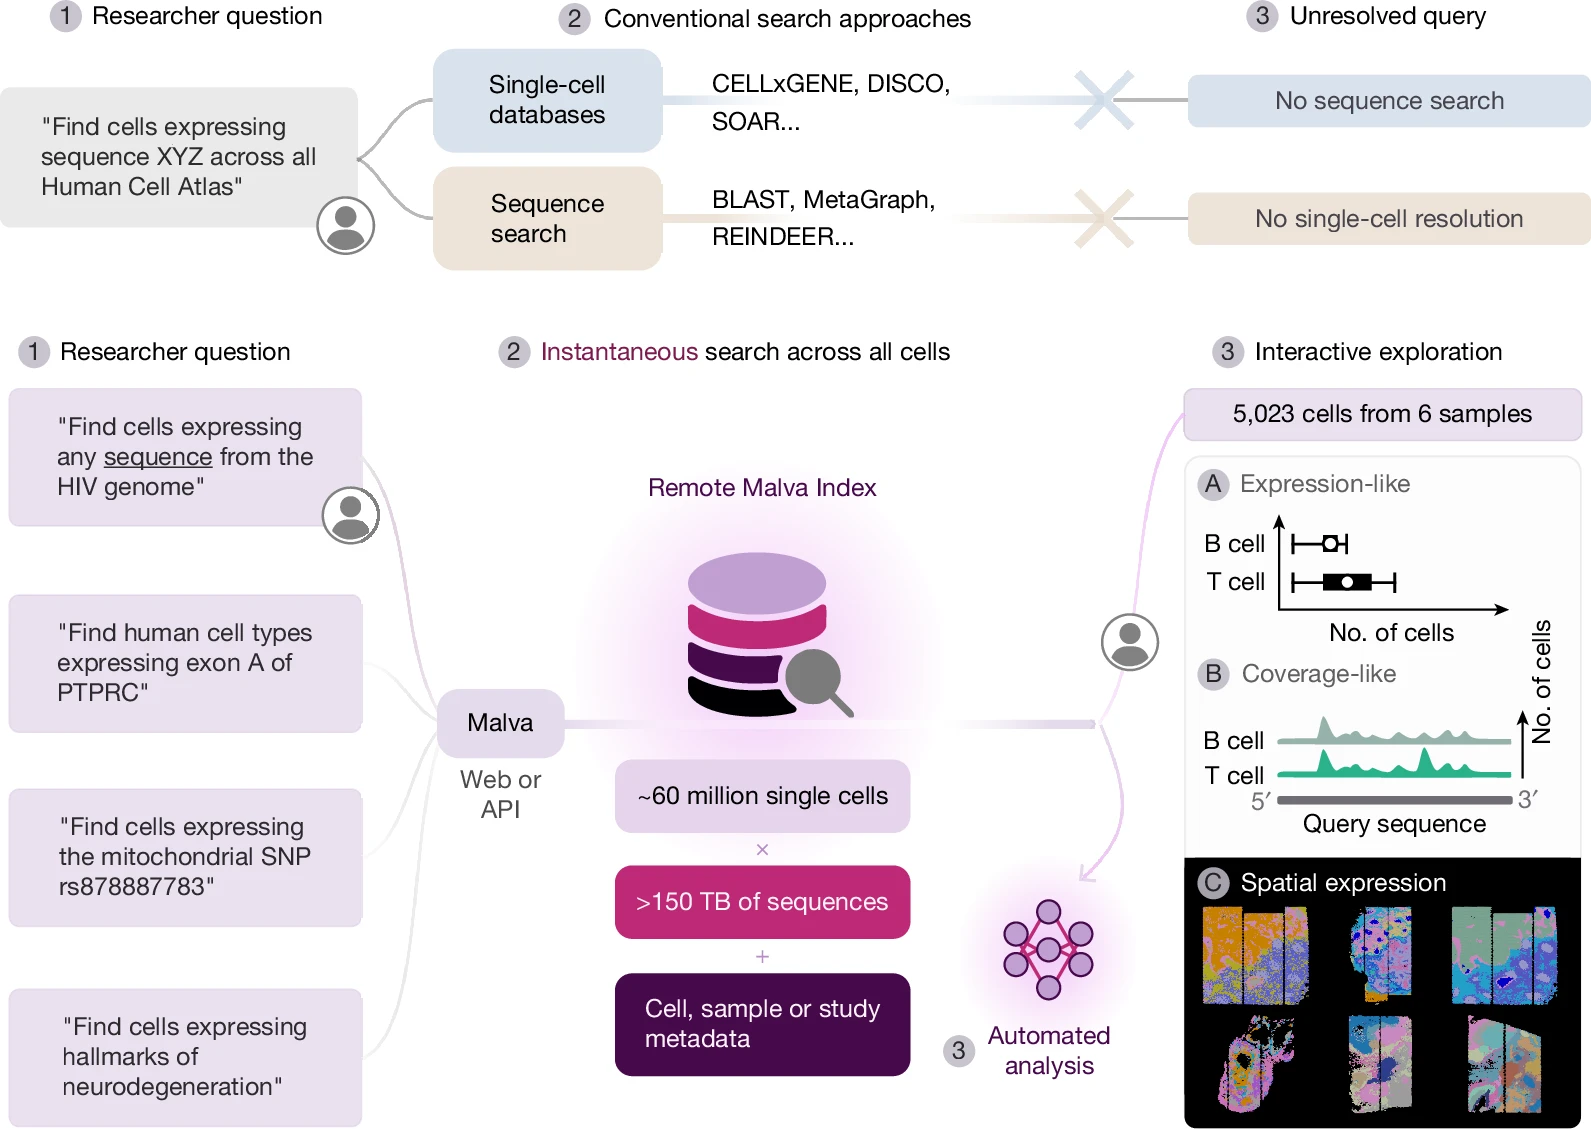
Conventional single-cell portals lack sequence-level resolution and existing sequence search tools lack single-cell resolution. Malva integrates these tools, providing real-time results at atlas scale. Researchers can query Malva Index using raw nucleotide sequences, gene symbols or natural language descriptions. Malva resolves these inputs to their underlying sequences and returns all matching cells together with rich metadata at both the cell and sample level (for example, cell types, disease status, sex, age and study identifiers). Results can be fed into computational systems for automated analysis (for example, neural networks) or analysed interactively, for example as expression distributions across cell types (A), coverage profiles along the queried sequence queries (B) or spatial maps when coordinates are available (C).
Searching RNA sequences across millions of cells
Malva is designed to search raw single-cell and spatial transcriptomics data without requiring a reference genome or transcriptome. Instead of limiting researchers to predefined genes and transcripts, the platform allows them to search for essentially any nucleotide sequence.
Researchers can use Malva to look for specific RNA sequences, mutations, splice junctions, pathogens, or transcripts associated with particular spatial locations. Searches can begin with a nucleotide sequence, a gene identifier, or even a natural-language description.
The Malva Index currently includes tens of millions of cells collected from thousands of experiments involving healthy and diseased tissues. The platform organizes raw sequencing information into searchable sequence fragments, allowing queries across very large datasets in seconds rather than requiring researchers to download and process the underlying files themselves.
Moving beyond reference-based RNA sequencing analysis
A major feature of Malva is that it can operate without relying on an existing reference. Traditional RNA sequencing pipelines typically align reads to known genes or transcripts before calculating expression levels.
Malva instead preserves access to the nucleotide sequences themselves. This makes it possible to investigate biological features that may not be represented in existing annotations, including previously unknown transcripts, alternative splice forms, sequence variants, and foreign sequences such as viruses or other pathogens.
The researchers also demonstrated that sequence composition alone could be used to identify cell types and evaluate similarities between cells. Malva can perform reference-free clustering and can assemble cell-type-specific sequences directly from indexed data.
Turning single-cell atlases into searchable sequence resources
Malva does not replace conventional gene-expression pipelines. Those approaches remain useful when researchers want to compare expression levels of known genes. Instead, Malva adds another layer of analysis by making the original sequence information accessible at very large scale.
The platform can also connect its search results with neural networks and automated analysis systems. This could make large single-cell RNA sequencing collections more useful for discovering mutations, alternative RNA isoforms, pathogens, and other sequence features that are difficult to investigate using standard gene-count datasets alone.
By allowing researchers to search directly through raw RNA sequences across millions of individual cells, Malva turns large single-cell atlases from largely static collections of expression measurements into searchable, sequence-resolved biological resources.
Availability – The Malva platform is accessible at https://malva.mdc-berlin.de.
León-Periñán D, Karaiskos N, Rajewsky N. (2026) Ultrafast and reference-free sequence discovery in single-cell data. Nature [article]
Related Posts





Single-cell RNA sequencing has made it possible to measure gene activity in millions of individual cells. Large projects such as the Human Cell Atlas are using these technologies to build detailed maps of healthy and diseased tissues.
However, most RNA sequencing analysis pipelines convert raw sequencing data into gene or transcript counts. This makes the data easier to analyze, but much of the original sequence-level information is no longer readily searchable. Researchers who want to look for a particular mutation, splice junction, pathogen sequence, or previously uncharacterized RNA may need to download and reprocess enormous amounts of raw data.
Researchers from the Max Delbrück Center for Molecular Medicine, Germany have now developed a computational platform called Malva to make this sequence information directly searchable.
Malva enables instantaneous sequence-based queries across single-cell atlases
Conventional single-cell portals lack sequence-level resolution and existing sequence search tools lack single-cell resolution. Malva integrates these tools, providing real-time results at atlas scale. Researchers can query Malva Index using raw nucleotide sequences, gene symbols or natural language descriptions. Malva resolves these inputs to their underlying sequences and returns all matching cells together with rich metadata at both the cell and sample level (for example, cell types, disease status, sex, age and study identifiers). Results can be fed into computational systems for automated analysis (for example, neural networks) or analysed interactively, for example as expression distributions across cell types (A), coverage profiles along the queried sequence queries (B) or spatial maps when coordinates are available (C).
Searching RNA sequences across millions of cells
Malva is designed to search raw single-cell and spatial transcriptomics data without requiring a reference genome or transcriptome. Instead of limiting researchers to predefined genes and transcripts, the platform allows them to search for essentially any nucleotide sequence.
Researchers can use Malva to look for specific RNA sequences, mutations, splice junctions, pathogens, or transcripts associated with particular spatial locations. Searches can begin with a nucleotide sequence, a gene identifier, or even a natural-language description.
The Malva Index currently includes tens of millions of cells collected from thousands of experiments involving healthy and diseased tissues. The platform organizes raw sequencing information into searchable sequence fragments, allowing queries across very large datasets in seconds rather than requiring researchers to download and process the underlying files themselves.
Moving beyond reference-based RNA sequencing analysis
A major feature of Malva is that it can operate without relying on an existing reference. Traditional RNA sequencing pipelines typically align reads to known genes or transcripts before calculating expression levels.
Malva instead preserves access to the nucleotide sequences themselves. This makes it possible to investigate biological features that may not be represented in existing annotations, including previously unknown transcripts, alternative splice forms, sequence variants, and foreign sequences such as viruses or other pathogens.
The researchers also demonstrated that sequence composition alone could be used to identify cell types and evaluate similarities between cells. Malva can perform reference-free clustering and can assemble cell-type-specific sequences directly from indexed data.
Turning single-cell atlases into searchable sequence resources
Malva does not replace conventional gene-expression pipelines. Those approaches remain useful when researchers want to compare expression levels of known genes. Instead, Malva adds another layer of analysis by making the original sequence information accessible at very large scale.
The platform can also connect its search results with neural networks and automated analysis systems. This could make large single-cell RNA sequencing collections more useful for discovering mutations, alternative RNA isoforms, pathogens, and other sequence features that are difficult to investigate using standard gene-count datasets alone.
By allowing researchers to search directly through raw RNA sequences across millions of individual cells, Malva turns large single-cell atlases from largely static collections of expression measurements into searchable, sequence-resolved biological resources.
Availability – The Malva platform is accessible at https://malva.mdc-berlin.de.
León-Periñán D, Karaiskos N, Rajewsky N. (2026) Ultrafast and reference-free sequence discovery in single-cell data. Nature [article]
Related Posts
Recent Posts
 Benchmarking RNA sequencing for more accurate alternative splicing analysis
 RNA Sequencing identifies new tick-borne virus that causes flu-like illness
 Eclipsebio expands its RNA characterization capabilities with multi-attribute nanopore-based sequencing assay eSTRAND RNA QC™
 Single-cell RNA sequencing links genetic mutations to cell behavior in cancer
 Small RNA sequencing reveals regulatory roles for sdRNAs in acute myeloid leukemia
 Creative Biolabs expands advanced single-cell multi-omics and RNA sequencing solutions to support biomedical discovery
RNA-Seq Products & Services


Stay Connected